Abbreviations:
- Xplain Data CausalDiscoverer : XCD
- Xplain Data ObjectAnalytics : XOA
- Xplain Data ObjectExplorer : XOE
- Xplain Data AdminTool : XAT
- Causal Discovery (CD)
Content: What is ObjectAnalytics, what it is not and why it is needed for Causal Discovery!
What are best practices / guidelines for a successful data import / analysis?
What is XOA?
- XOA means restructuring data, which usually comes from a relational database or similar, with a certain focus entity in mind (The Patient, the Machine Part, the Employee…). Data entities are treated as objects, instead of flat tables or dataframes. Check the explanations in the Video or this text for some more details. While this restructuring needs a little bit of preparation in the beginning, it will pay off hugely in the long run by having all relevant information for each object readily available. Moreover, the restructuring needs to be done only once and can then also be used in future projects and does not have to be adjusted for some other use case! This leads to greater flexbility, more powerful analyses, and a significant improvement in computation times. It is only with this boost that Causal Discovery can reasonably be applied on complex real-world data!
Why should I use XOA instead of any standard approach?
- Most real-world data is quite complex and contains high-dimensional dependencies between various entities (Diagnoses-Prescriptions, Measurements-Product Quality etc.). Tipically, before being able to start with some Data Analytics, this complex information has to be summarized into one big data frame, or “flat table”, as this is the form of input that methods from standard frameworks expect. However, flattening complex, multi-table data into one dataframe will always lead to a loss of information or introduce bias (examples will follow further below)!
- On the other hand, with XOA you can load and store the data as they come in their natural form, therefore admitting a complete 360°-view of the object in focus without throwing any of the available information and dependencies away.
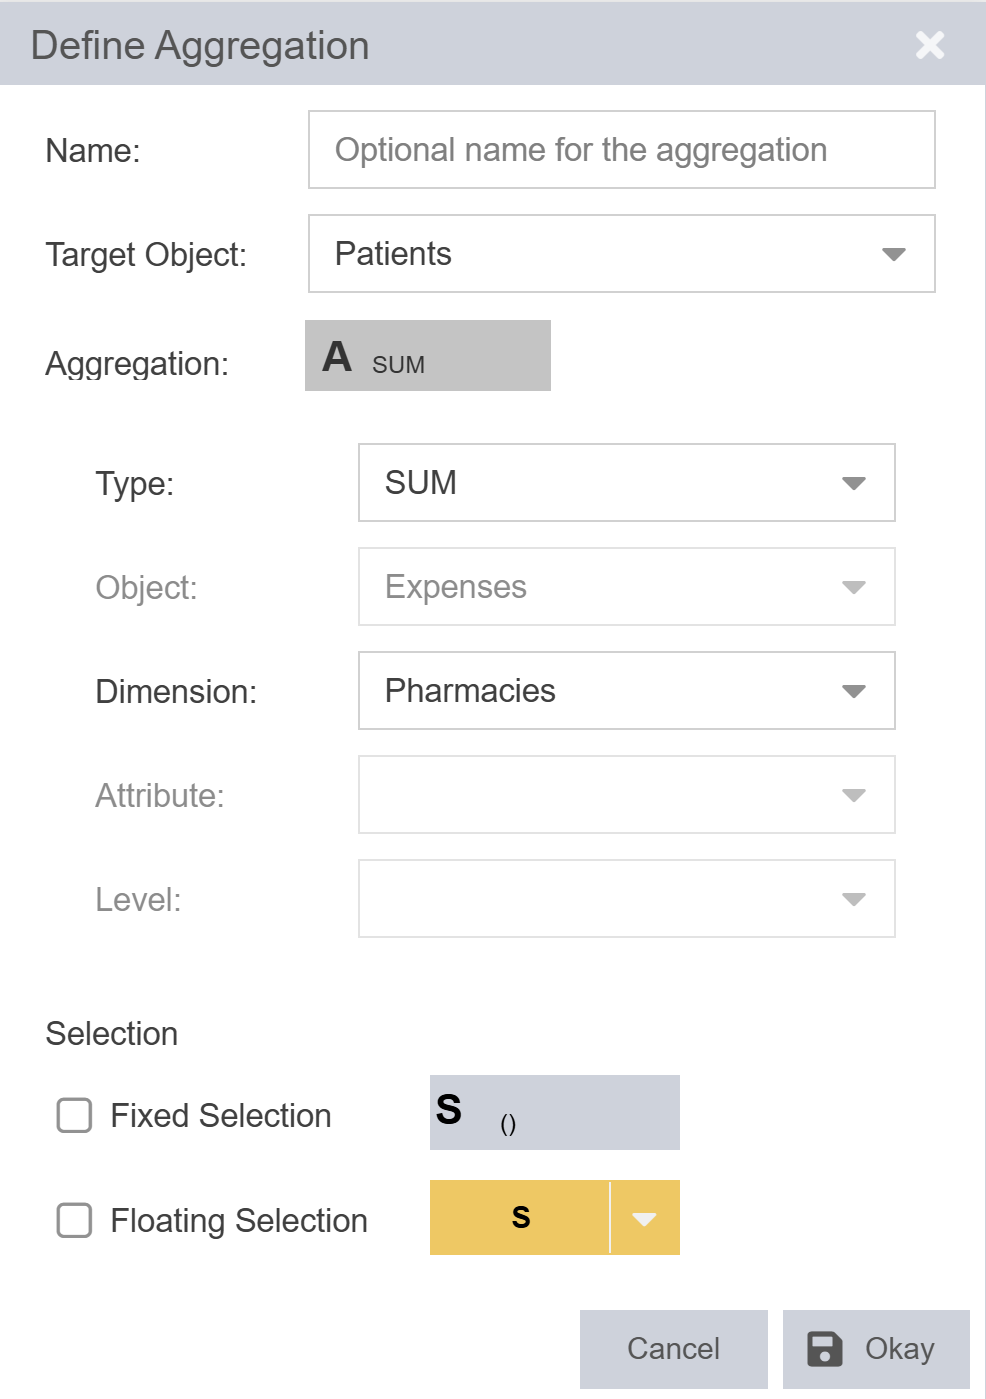
- Storing data as objects instead of flat tables means that all relevant information for an object is readily available and does not have to be looked up first. With this 360° view it is very easy and natural to build variables or features over multiple (sub-)objects, which would tipically have to be done via some quite convoluted queries. For instance,
- the sum of Total Prescription Costs after a certain Diagnosis
- the maximum force applied to a Machine part before a certain Production Step.
- the number of Events which have happened for any Item on a Purchase Document
There are virtually infinitely many ways to aggregate data over objects and build features. With all data for one object stored jointly, these can be computed with only a couple of quick and therefore much faster than in a relational database.
- Storing data as objects instead of flat tables / dataframes leads to a significant improvement in compuation times and scalability, which is especially important for Causal Discovery. Typical CD algorithms do not perform well on complex real-world data, as there are potentially millions and millions of possible variables/features to be considered as confounders. Standard algorithms simply cannot handle tables with millions of columns. In fact, the number of variables/columns typically is reduced beforehand by a domain-expert, which is prone to introducing bias! On the other hand, XCD is able to incorporate all of the available data over the whole lifetime of our object in focus and hence assure that no confounders are left out. It is only then that you can be reaonably sure to have found an actual causal relationship. Therefore, ObjectAnalytics makes Causal Inference feasible in a complex real-world environment.
How does my data have to look like such that XOA is as performant as possible?
- XOA particularly thrives when using complex real-world data, for example from a relational database. The more sub-objects with some interdependencies are appended to a root-object, the more XOA can show its strengths by computing meaningful features and uncover relationships over these sub-objects. Typically, these sub-objects are streams of events (diagnoses, prescriptions, measurements, (electrical) tests etc., depending on your use case). The best-case scenario is that each of these sub-objects also has timestamps appended to it. This ensures that events will be considered in the correct (causal) order!
How does XOA represent my data? What is an Object Tree?
- Each table in the source database for some entity in the process of interest can be regarded as an object. One of these has to be defined as the root object and others may be appended as sub-objects. For example, the “Patient”-object is suited as the root, and it has the “Diagnoses” and the “Prescriptions”-object appended to it as sub-objects. Another typical industry example for a root object is a “Produced Part”, where its important sub-components and measurements/tests can be regarded as its sub-objects.
- Each of these objects is characterized by its own dimensions and attributes. Columns in the table are added to the corresponding objects and are called dimensions. These dimensions can be represented / discretized by various attributes (see also 2. An introduction to the XOE — Xplain Data Manual documentation).
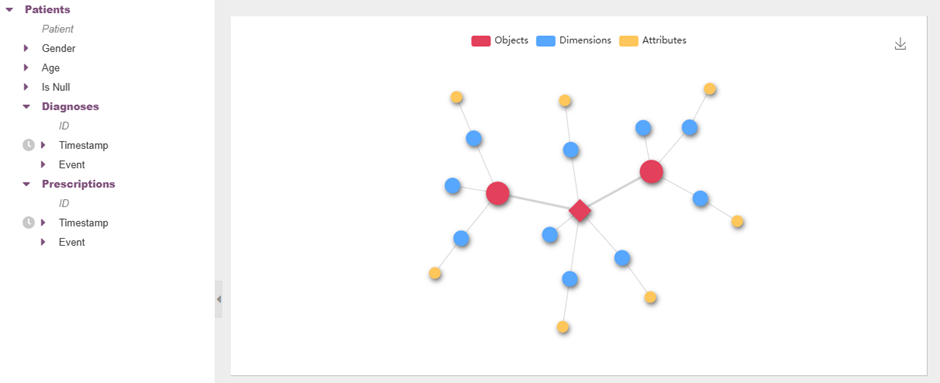
- Such a hierarchical representation of the data is called an ObjectTree or ObjectModel. Note that this way the available information from the original database has been rearranged such that each object now contains all relevant information, which is related to it, meaning that this information does not have to be looked up tediously, when it is needed.
- Once this work has been done, the same ObjectTree can now be used for any other use case. We do not have to design a completely new dataframe with hand-picked features, as it would be the case in traditional data science projects. Note that preprocessing typically is the most time-consuming part of each Data Science project. We therefore gain not only flexibility, but save a lot of time and effort in the long run!
- On the other hand, the ObjectModel may always be updated both vertically, meaning appending new data records, and horizontally, meaning adding some more objects.
Why is the data stored as Objects? Couldn’t I also represent the same data as a flat table?
- Somehow you could try, but you would be forced to transform the data in some way. In particular, there is no unique way to do it, so you actually run the high risk of not transforming it “correctly” and therefore introducing bias into your model! Each object itself can be represented easily as a table, but remember that here we are working with a main object in focus, meaning that the information from its sub-objects needs to be mapped onto it somehow. Now how do we append the sub-object data to the root object? Note that there are a number of issues arising - firstly, the number of sub-object events might be different for each object and secondly, how to we deal with time-dependent data? In our health example with the “Patient” root-object and “Diagnoses” / “Prescriptions” sub-objects, do we have to append a column for each single diagnosis and each timestamp, say

and also do the same for all prescriptions? Since every patient has a different number of diagnoses and prescriptions, we would have to consider the patient with the most diagnoses/prescriptions and create that many columns. This means, firstly, that the table will have a huge number of columns and, secondly, that many columns will stay empty for many patients / rows.
- Another way to do it would be to compute aggregations/features from the data, for example, the number of diagnoses, the sum of total prescription costs etc. and add them as columns to the table. But how can we really know beforehand which are the “correct” features to build?
- In other words, while the object-centric view allows a whole 360° view of the object in focus and retains all the available information, a flat table representation of the same data will always be like a 2-dimensional projection of a 3-dimensional object! Flattening data throws information away and introduces bias!
Where can I define my ObjectTree?
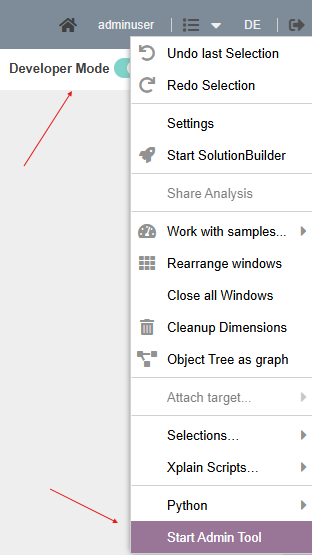
- By creating an ObjectView in the AdminTool (XAT) (see the docu material there or here). Simply toggle the Developer Mode and start it from the XOE.
How do I have to preprocess my data before being able to create an ObjectView?
- If there are no inconsistencies (for example inconsistent data types within a column) in the data, the only thing to check is if there are unique IDs, which can connect an object to its parent(s). If this is not the case, these IDs might have to be created manually. Typically, this can be done by joining one or more column names to a new one. Otherwise, no preprocessing has to be done. The data can be loaded into the XOE as a whole, we don’t even have to worry about missing values!
What do I have to think about before defining an ObjectView?
- The input needed by the user is the hierarchical structure of the data, i.e. the ObjectTree or ObjectModel. This means in particular to decide which of the available objects is the main object in focus, and in which order the sub-objects should be appended. Typically, a domain expert will have a good intuition for a meaningful data structure, and the root objects usually just follow from the particular analysis question you have in mind - Why do Patients get sick? Why do I have Produced Parts that are broken? Why do Customers churn? Why is my Process non-compliant etc.
Can I redefine my root-object on the fly? How flexible is the ObjectTree?
- Object Trees cannot be redefined directly in the XOE. They have to be defined first with the AdminTool via a so called ObjectView. Another ObjectView has to be created to that end. However, via the AdminTool, an already existing ObjectView can easily be redefined to alter its hierarchy (by redefining the keys).